Back to the lesson·Lesson 6 of 8·Working the table
Grouping to a numerator and a denominator
The same deck as the downloads, rendered as a page. Start the slideshow to present it full screen — arrow keys or a click advance one slide, Escape leaves.
What this lesson covers
- An indicator is two numbers
- Named aggregation
- Two defaults that change a denominator
- Grouping by more than one key
- transform: a group statistic on every row
- apply, and why to avoid it
- Pivot tables read better for a report
- Writing the result out
- What comes next
Speaker notes
groupby, named aggregation, and the two defaults that silently change a denominator — dropped missing groups and unobserved categories. Producing both halves of an indicator in one operation so they cannot drift.An indicator is two numbers — In Python (cont.)
import pandas as pd

muac = read_register(RAW / "muac-screening-artibonite-2024.v1.csv")

measured = muac["muac_mm"].notna()
gam = measured & (muac["muac_mm"] < 125)

by_commune = (
    muac.assign(measured=measured, gam=gam)
    .groupby("commune")
    .agg(
        screened=("child_id", "size"),
        measured=("measured", "sum"),
        gam_cases=("gam", "sum"),
    )
)
Speaker notes
Almost every figure this sector reports is a numerator over a denominator, and almost every argument about a figure is an argument about the denominator. The practical consequence for your code: compute both in the same operation. Two separate calculations drift. One gets a filter the other does not, someone edits one line, and the ratio becomes a number nobody can reconstruct.An indicator is two numbers — In Python (cont.)
by_commune["gam_rate"] = (by_commune["gam_cases"] / by_commune["measured"]).round(3)An indicator is two numbers — Example
             screened  measured  gam_cases  gam_rate
commune
Gros-Morne        361       351         48     0.137
Anse-Rouge        229       223         30     0.135
L-Estere          189       187         18     0.096
Terre-Neuve       241       235         21     0.089
Speaker notes
Three columns and every one of them is load-bearing.screenedis how many children came;measuredis how many produced a usable MUAC and is the denominator;gam_casesis the numerator. Publishing the rate without the denominator beside it is how the argument starts. Note thatscreenedandmeasureddiffer — 4,218 children were screened and 4,146 have a MUAC. Dividing by the wrong one shifts the district rate by enough to matter and by too little to notice.Named aggregation — In Python
.agg(
    output_name=("input_column", "function"),
    ...
)
Speaker notes
The form used above is the one to standardise on:Named aggregation — In Python
muac.groupby("commune")["muac_mm"].mean()               # one column, one function
muac.groupby("commune").agg({"muac_mm": ["mean", "std"]})  # MultiIndex columns
Speaker notes
It names the output column at the point the aggregation is defined, so there is no second step renamingmuac_mm_meanto something a reader understands, and no multi-level column index to flatten. The older forms still work and are worth recognising in someone else's code:Named aggregation — In Python
def share_below(series, threshold=125):
    valid = series.dropna()
    return (valid < threshold).mean() if len(valid) else float("nan")

muac.groupby("commune").agg(
    gam_rate=("muac_mm", share_below),
    n=("muac_mm", "count"),
)
Speaker notes
The second produces columns like("muac_mm", "mean"), which then need flattening. Named aggregation avoids the problem rather than solving it. Functions can be your own:countexcludes missing;sizeincludes them. That single distinction is the difference between the two denominators above, and it is worth saying out loud every time you use one.Two defaults that change a denominator
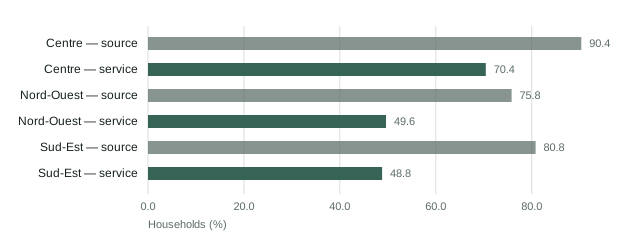
Improved water source against basic service, by district. Counting sources overstates coverage everywhere; the gap is households whose source is improved and more than thirty minutes away. Two defaults that change a denominator
- Missing group keys are dropped
Speaker notes
Both bars in each pair come from the samegroupby. The only difference is which rows the numerator counts — and it moves the answer by twenty to thirty points in every district. That is what "the denominator is the point" means in practice.Two defaults that change a denominator — In Python
d = pd.DataFrame({"g": ["a", None, "a"], "v": [1, 2, 3]}) d.groupby("g")["v"].sum() # {'a': 4} d.groupby("g", dropna=False)["v"].sum() # {'a': 4, nan: 2}Two defaults that change a denominator — In Python
assert muac["commune"].notna().all(), "rows with no commune would be dropped"Speaker notes
By defaultgroupbydiscards rows whose group key is missing. They vanish from the table and from the total, so the parts no longer sum to the whole and nothing says why. In this sector the missing key is usually the interesting one: a facility with no district recorded, a household with no site code, a child with no commune. Usedropna=Falseand decide deliberately, or assert the key is complete:Two defaults that change a denominator
- Unobserved categories reappear as empty rows
Speaker notes
If the group key is categorical, the default is now to return only observed categories:Two defaults that change a denominator — In Python
c = pd.DataFrame({"k": pd.Categorical(["x", "y"], categories=["x", "y", "z"]), "v": [1, 2]}) len(c.groupby("k", observed=True)["v"].sum()) # 2 len(c.groupby("k", observed=False)["v"].sum()) # 3 — includes an empty "z"Two defaults that change a denominator
- Pass it explicitly — The default changed between pandas versions, and a script that relies on it produces a different…
Speaker notes
Both are right for different questions. Reporting on facilities that submitted data wantsobserved=True; reporting coverage against a list of facilities that should have submitted wantsobserved=False, because a facility with zero rows is the finding. Pass it explicitly. The default changed between pandas versions, and a script that relies on it produces a different table on a colleague's machine.Grouping by more than one key — In Python
by_commune_month = ( muac.assign(month=muac["screening_date"].dt.to_period("M"), gam=gam) .groupby(["commune", "month"], observed=True) .agg(measured=("muac_mm", "count"), gam_cases=("gam", "sum")) )Grouping by more than one key — In Python
by_commune_month.loc["Gonaives"]                      # one commune, all months
by_commune_month.reset_index()                        # back to flat columns
Speaker notes
The result has a MultiIndex. Two ways to work with it:Grouping by more than one key — In Python
wide = by_commune_month["gam_cases"].unstack("month", fill_value=0)Speaker notes
reset_index()before writing to CSV, always — otherwise the index columns either disappear or arrive unnamed. To turn the long result into the wide table a report wants:fill_value=0is safe here because a commune-month with no cases genuinely had zero. It would be wrong for a rate, where the absence means "not computed", not "zero percent" — a distinction worth checking every time you reach for it.transform: a group statistic on every row — In Python
muac["commune_mean"] = muac.groupby("commune")["muac_mm"].transform("mean")
muac["vs_commune"] = muac["muac_mm"] - muac["commune_mean"]
Speaker notes
aggcollapses;transformreturns a value per original row. This is how you compare a row against its own group without a join: Useful for flagging a site whose measurements sit systematically away from the rest — which is exactly the check the SMART survey analysis project uses to find a team measuring 0.5 kg light.apply, and why to avoid it — In Python
# Works, but slow, and returns something whose shape depends on the function.
muac.groupby("commune").apply(lambda g: g["muac_mm"].mean(), include_groups=False)
Speaker notes
applyruns a Python function per group and is the slowest thing in pandas by a wide margin. It is also the most flexible, so it is what people reach for first. Prefer a named aggregation. Reach forapplywhen the operation genuinely needs the whole group frame — a per-group regression, a per-group ranking with ties broken on a second column — and passinclude_groups=False, which is now required to avoid the grouping columns being handed to your function.Pivot tables read better for a report — In Python
pd.crosstab(muac["commune"], muac["outcome"])

pd.crosstab(
    muac["commune"], muac["outcome"],
    values=muac["muac_mm"], aggfunc="mean",
).round(1)
Speaker notes
pivot_tableisgroupbyplusunstackwith a friendlier signature:crosstabwithnormalize="index"gives row proportions, which is usually what a referral table should show. Keep the counts beside them: a 50% referral rate on four children is a different fact from 50% on four hundred, and only the count distinguishes them.Writing the result out — In Python
OUTPUTS = PROJECT / "outputs" / "tables" OUTPUTS.mkdir(parents=True, exist_ok=True) by_commune.reset_index().to_csv(OUTPUTS / "gam_by_commune.csv", index=False)Writing the result out — In Python
definitions = pd.DataFrame([
    ("GAM", "MUAC < 125 mm or bilateral pitting oedema",
     "children with a MUAC measurement or a recorded oedema assessment"),
], columns=["indicator", "numerator", "denominator"])

definitions.to_csv(OUTPUTS / "definitions.csv", index=False)
Speaker notes
index=Falseafterreset_index()— otherwise you get an unnamed integer column that someone will later open in Excel and sort by. For a table someone will read rather than compute on, write the definition with it: A number and its definition travel together, or the monthly argument about the denominator starts again.What comes next
- The table aggregates correctly and both halves of every rate come from one operation.
Speaker notes
The table aggregates correctly and both halves of every rate come from one operation. The next unit gets the last piece right — dates, ages and reporting periods, where an age in months decides which growth standard applies — and then wraps the whole thing in a script that runs on someone else's machine.